Self-Attention Visualizer
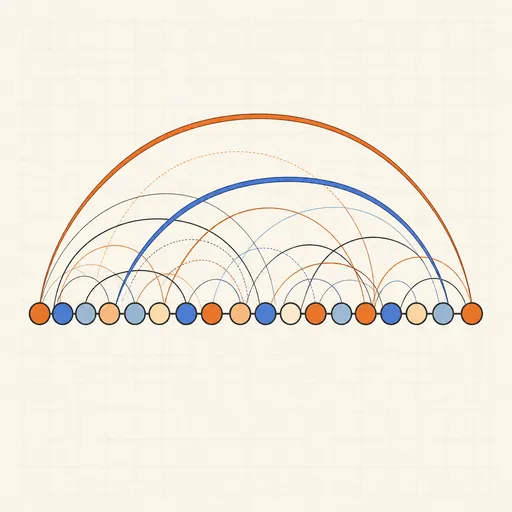
Self-attention is the mechanism at the heart of Transformers: every token looks at every other token and decides how much to attend to it. Type a short sentence or pick a preset, and the tool tokenizes it, builds deterministic pseudo-embeddings with sinusoidal positional encodings, projects them through randomly seeded query/key/value matrices and computes scaled dot-product attention. Click any token in the arc diagram to see where it attends — line thickness equals attention weight — and read the full weight matrix on the heatmap, rows attending to columns. Switch between 1, 2 or 4 heads to see heads mix information differently, sharpen or soften the softmax with the scaling slider, and flip on the causal mask to see how GPT-style decoders block attention to future tokens.
Runs 100% in your browser — models are trained and computed locally on your device.
Read the full guide to this tool
Notes
- Scaled dot-product attention computes softmax(QKᵀ/√d)·V; dividing by √d keeps dot products from growing with dimension so the softmax stays in a usable range.
- Multi-head attention splits the embedding into independent subspaces; each head computes its own attention pattern and real models concatenate the resulting values.
- A causal (lower-triangular) mask sets scores above the diagonal to −∞, so each position attends only to itself and earlier tokens — the property that lets decoders generate text left to right.
- The projections here are random but seeded rather than learned, so the patterns reflect the geometry of the embeddings and positions; in a trained Transformer these matrices are learned end to end.
- Runs 100% in your browser — models are trained and computed locally on your device.
Related tools

Backpropagation Step-by-Step
Walk through one forward and backward pass of a tiny neural network, number by number.
Handwritten Digit Recognizer
Draw a digit and watch a neural network trained on MNIST recognize it live in your browser.
Neural Network Playground
Train a tiny neural network live in your browser and watch its decision boundary learn four classic datasets.
Activation Function Explorer
Compare sigmoid, tanh, ReLU and friends with their derivatives, and see why deep gradients vanish.
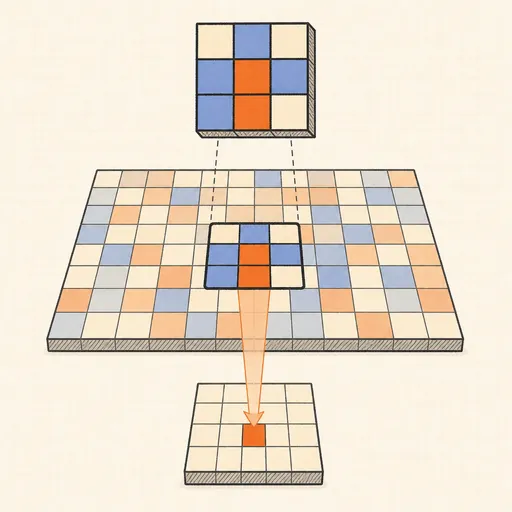
Convolution Filter Visualizer
Slide a 3×3 kernel over an image and watch convolution, ReLU and max-pooling build the output pixel by pixel.
Hopfield Network
Store pixel patterns in a Hopfield memory, corrupt them, and watch the network recall the original.